SMP Data Parallelism
In data parallelism, the same operations are performed in some sequence on different parts of the data. This typically expressed as a loop.
for (i=0;i<imax;i++) {
   a[i]=b[i]+c[i]
}
A Real-World Example
Building a brick wall in parallel with multiple masons working.
- Materials are delivered.
- The foreman assigns the work.
- Each mason lays brick in his assigned section.
- Overlap of regions done by different masons must be managed.
- Smooth joints between sections to make a unified whole.
We can see that for this procedure to work, all the masons must be coordinated. The brick pattern must be the same throughout the wall. The boundaries must be computed in advance and the appropriate size for each mason’s section, and the starting position of the brick layer, must be determined.
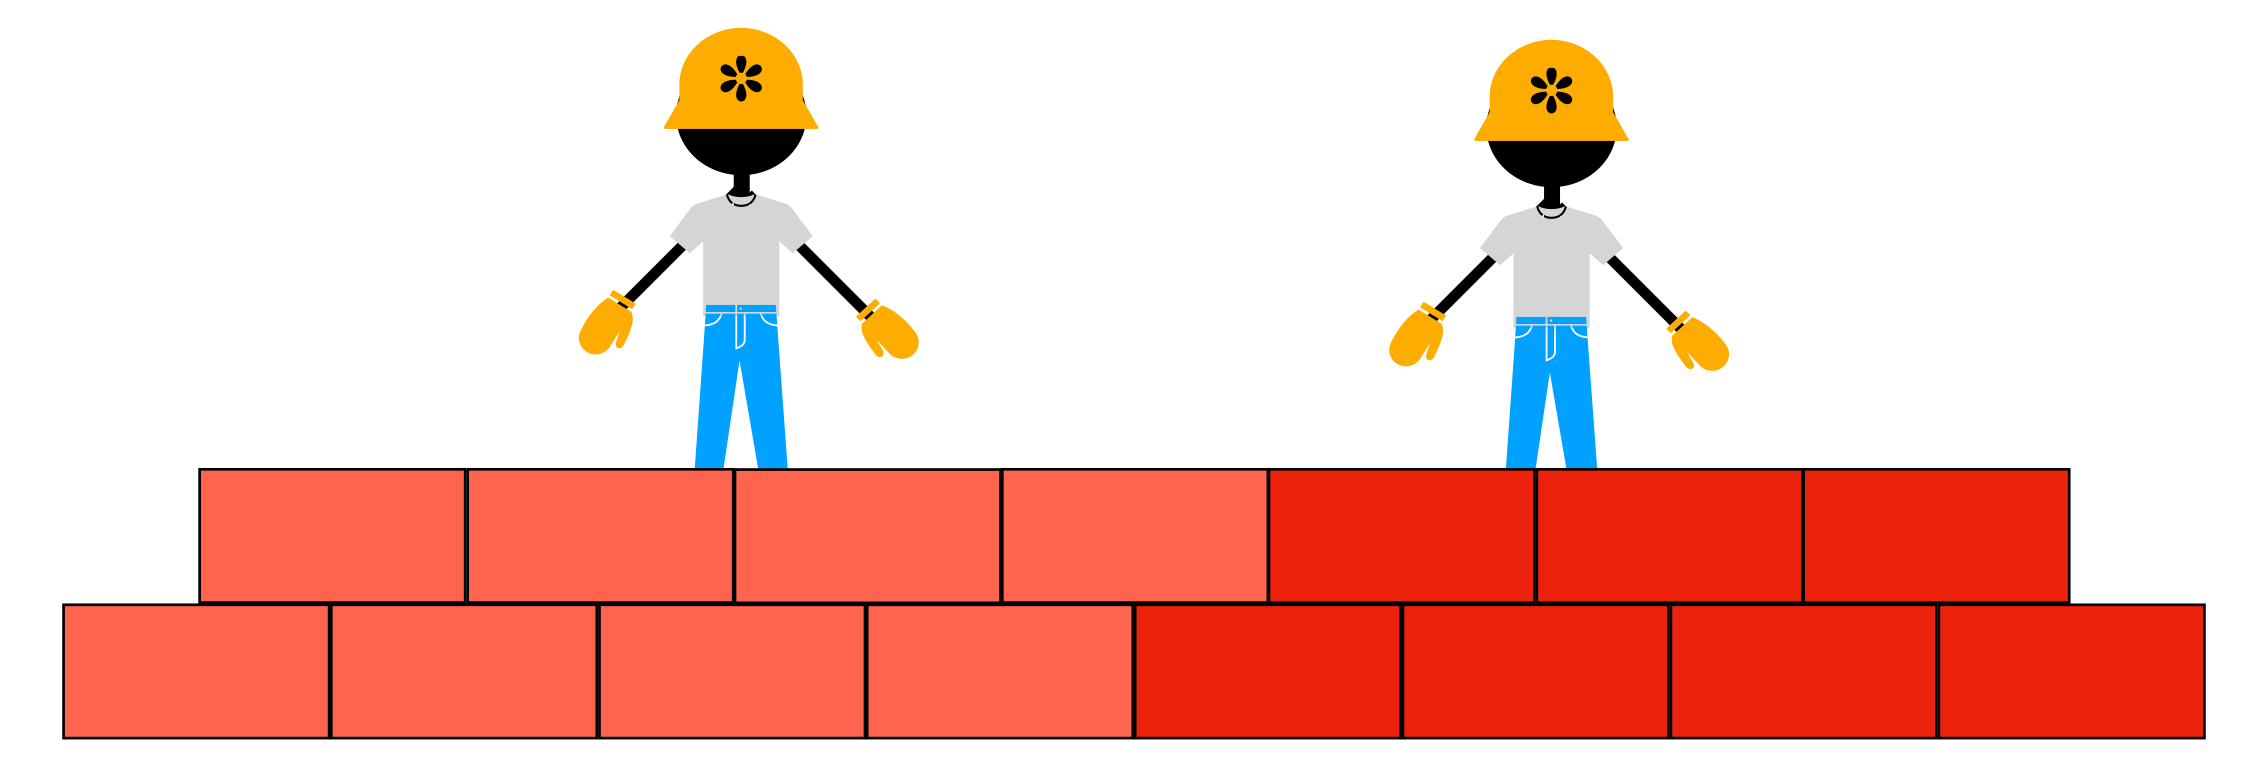
The time saving by laying bricks (or stones, or blocks) in parallel with multiple workers can be the difference between whether a project is feasible or not.
We can make this analogy to both distributed memory programming and shared memory programming. The main difference is that in distributed-memory programming the programmer is responsible for managing the work, whereas in most multithreading models the higher-level shared-memory programming libraries handle the distribution of work.
A Computational Example
Find the maximum of a function using a “brute force” method.
- Evaluate the function at a huge number of randomly-distributed points over a specified range of independent variables.
- Distribute these points out so that each process evaluates the function throughout the range.
- Each process computes the maximum of its sample.
- Individual maxima are returned to the master process, which selects the maximum of maxima as the result.
We have solved this problem using MPI. We can also solve it with threading, but we first need to study a threading programming model. We will start with the most popular for application programs, OpenMP.